Canonicals are the signals you give search engines to identify the preferred version of a URL when duplicate or near-duplicate pages exist. A canonical tag, implemented as rel=canonical in the page's HTML head, points Google and other crawlers to the canonical URL you want indexed and ranked. Without canonicals, search engines split ranking signals across multiple URLs that serve essentially the same content, which dilutes authority and wastes crawl budget.
Key takeaways
- A canonical tag is an HTML hint that tells Google which URL should rank when duplicate pages exist.
- Use canonicals for www vs non-www, HTTP vs HTTPS, trailing slashes, tracking parameters, and syndicated content.
- Place the tag in the section with an absolute URL, and avoid chains, conflicts, and dead-end targets.
- Verify your choice in Google Search Console's URL Inspection tool, and keep internal links and sitemaps aligned with the canonical URL.
- Automated audits catch missing or conflicting canonicals across large sites before they dilute rankings.
Think of a product page reachable through three different URLs: one with tracking parameters, one from a category filter, and one with a trailing slash. The content is identical, but Google sees three separate pages. The canonical tag consolidates those signals by declaring one URL as the master copy. The rel=canonical attribute sits inside a <link> element in the <head> section, and it looks like this:
<link rel="canonical" href="https://example.com/product/blue-widget/" />That single line tells Google: when you encounter any duplicate of this page, treat the specified canonical URL as the source of truth. The canonical URL is not a redirect. Users still land on whichever URL they clicked, but ranking credit flows to the version you designated. This distinction matters because canonicals preserve user experience while cleaning up how search engines interpret your site structure. A well-placed canonical tag prevents the confusion that arises when the same article appears under both /blog/post-title and /blog/post-title?utm_source=newsletter, ensuring one clean entry in the index instead of several competing ones.
Why Canonicalization SEO Matters
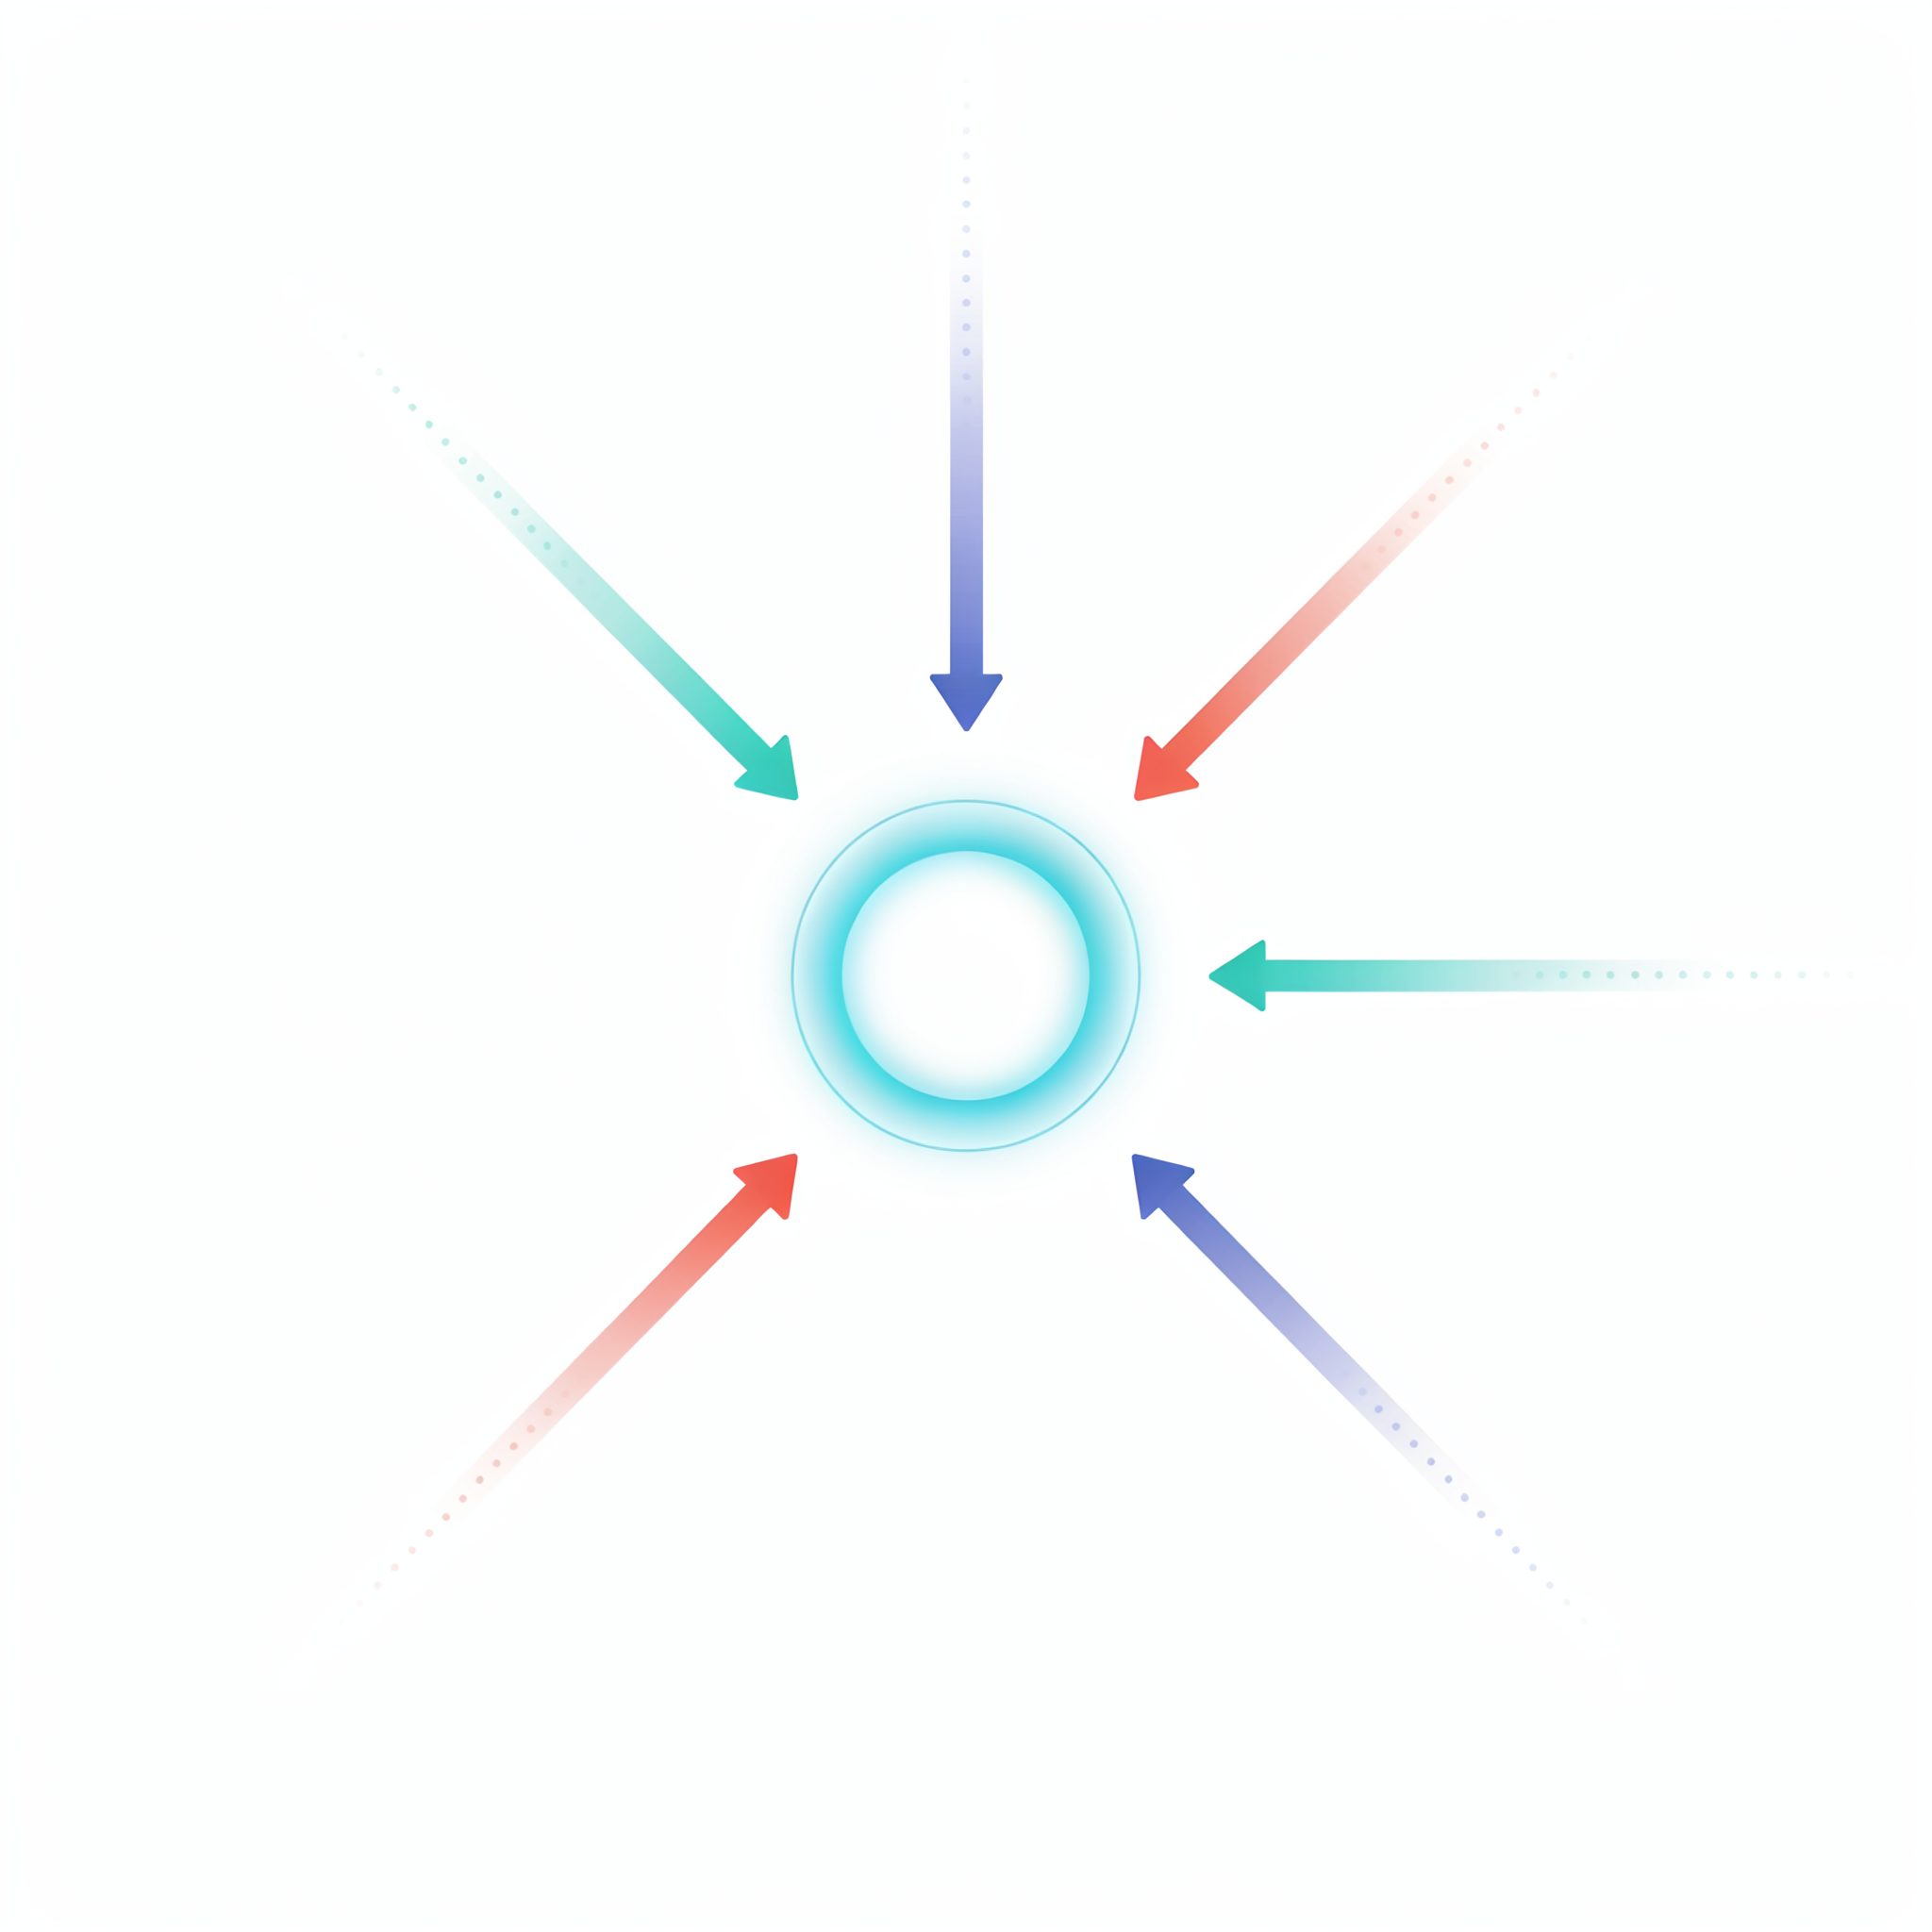
Duplicate content splits ranking signals. When Google finds the same article on two URLs, it has to choose which one to show. Links, authority, and user signals get divided between them. Neither page ranks as well as a single consolidated version would. Canonicalization SEO fixes this by telling Google which URL is the real one, so all those signals point to one place.
Without canonicals, you lose control of which version appears in search results. A product page reachable through filters, tracking parameters, or a trailing slash can generate several near-identical URLs. Google might pick the wrong one, or it might index several and dilute your page's authority. The fix is a rel=canonical tag, which consolidates ranking signals onto your preferred URL.
This matters for crawl efficiency too. Googlebot wastes crawl budget on duplicate pages that add no value. When canonicals are in place, the crawler understands which URLs deserve attention and which are just variations. For large sites with thousands of product pages, that's the difference between fresh content getting indexed quickly and important pages sitting in the queue. Serfix's Websites and SEO: The Essential Guide to Search Friendly covers how crawl budget and site structure interact, but the short version is that canonicalization SEO keeps Google focused on the pages that actually matter.
Rankings drift without canonicals. A page that should be on page one might sit on page three because its authority is split across four duplicate URLs. Fixing that with a canonical tag often produces a quick, measurable lift, because you're not earning new links, you're just pointing the ones you already have at the right target.
How the rel=canonical Tag Works
The rel=canonical tag is a small piece of HTML you place in the <head> section of a page. It tells search engines which URL should be treated as the primary version when similar or identical content exists at multiple addresses. The syntax looks like this:
<link rel="canonical" href="https://example.com/preferred-page/" />That single line points to the canonical URL, the version you want indexed. Search engines read it as a strong signal, not an absolute command. Google usually respects it, but it can choose a different canonical if signals conflict.
Placement matters. The tag belongs in the <head>, not the <body>. If you put it in the wrong place, search engines may ignore it. Most CMS platforms, including WordPress with an SEO plugin, handle this automatically.
Canonicals differ from redirects in one key way. A 301 redirect sends both users and crawlers to a new URL, removing the old page from the equation. A canonical tag keeps the duplicate page live and accessible while telling crawlers where the authority should consolidate. Users can still visit the non-canonical URL.
Noindex works differently too. A noindex tag tells search engines not to index a page at all. A canonical tag says "index this other version instead." Using both on the same page sends mixed signals. If you noindex a page, you generally don't need to canonicalize it, and vice versa.
For sites managing many pages, tools like Content AI Autopilot can help keep canonical tags consistent across large content libraries without manual checking.
When to Use Canonicals
Canonicals solve a specific problem: the same content living at more than one URL. Search engines treat each URL as a separate page unless you tell them otherwise, and that splits ranking signals across near-identical copies. You don't need a canonical tag on every page, but you do need one whenever a duplicate or near-duplicate exists for a reason you can't eliminate.
The most common scenario is the www versus non-www split. If https://example.com/page and https://www.example.com/page both return the same article, pick one as the canonical URL and point the other at it. The same logic applies to HTTP versus HTTPS. Once your site has an SSL certificate, every HTTP URL should carry a rel=canonical tag pointing to its HTTPS equivalent, even if you also set up server-side redirects. Canonicals act as a second signal that reinforces the redirect.
Trailing slashes are another quiet source of duplicate content canonical issues. https://example.com/blog/ and https://example.com/blog can both resolve to the same page depending on your server configuration. Choose one convention, usually the trailing slash for directory-style URLs, and make the other variant canonicalize to it. Print-friendly pages, like a ?print=true version of an article, should also point back to the main page.
Parameter-heavy URLs are where canonicals earn their keep. E-commerce sites generate dozens of URLs from sorting, filtering, and session tracking: ?sort=price, ?color=blue, ?utm_source=newsletter. Most of these parameters don't change the core content, so the canonical tag should reference the clean URL without the tracking or cosmetic parameters. This consolidates signals and keeps crawl budget focused.
Syndicated content works the same way. If you publish an article on your site and a partner republishes it, the partner's version should include a rel=canonical tag pointing to your original. That tells Google which copy to rank. Without it, the partner's page can outrank yours, especially if their domain has more authority. The canonical tag is the mechanism that keeps the credit where it belongs.
How to Add a Canonical Tag
Adding a canonical tag depends on your platform. WordPress, Shopify, and static HTML each handle it differently, but the underlying principle stays the same: point the rel=canonical link element at the preferred canonical URL.
On WordPress, the cleanest route is a plugin. Yoast SEO and Rank Math both add a rel=canonical tag to every page automatically, using the page's permalink as the canonical URL. To override it, open the post or page editor, scroll to the SEO settings panel, and look for the "Canonical URL" field. Paste the full URL you want Google to treat as the original, including https://, then save. If you're comfortable editing theme files, you can also add this line to your header.php inside the <head> section: <link rel="canonical" href="https://example.com/preferred-page/" />. Most site owners find the plugin approach easier to maintain.
Shopify generates canonical tags automatically for products, collections, and pages, and it handles duplicate variants reasonably well. But there are cases where you'll want to override the default. For example, if a product appears in multiple collections with different URLs, Shopify usually picks the right one. To set a custom canonical URL on a Shopify page, you'll need to edit the theme's liquid template. In the theme.liquid file, find the <head> section and add: <link rel="canonical" href="{{ canonical_url }}" />. Shopify's canonical_url object outputs the store's default canonical, but you can replace it with a hardcoded URL for specific templates when needed.
For static HTML sites, you add the tag manually to each page's <head>. Open the HTML file, locate the <head> section, and insert the link element before the closing </head> tag. The format is always the same: <link rel="canonical" href="https://www.example.com/this-page/" />. Replace the href value with the exact URL you want indexed. If you use a static site generator like Hugo or Jekyll, you can set a canonical variable in the front matter and reference it in the layout template, so every page gets the tag without manual edits.
One detail worth checking across all platforms: use absolute URLs, not relative paths. A canonical tag pointing to /blog/post/ instead of https://example.com/blog/post/ can confuse crawlers and undermine your canonicalization SEO. After adding the tag, view the page source in your browser and search for rel=canonical to confirm it's rendering correctly. Serfix's site audit flags pages with missing or conflicting canonical tags, which saves you from manually checking every URL after a template change.
Common Canonical Mistakes
Most canonical problems aren't caused by a missing tag. They're caused by a tag that points somewhere it shouldn't. The fix is usually quick once you spot the error, but the symptoms can look like a slow rankings decline that's hard to trace.
A self-referencing error happens when a page's canonical URL points to a different page on the same site, often an old URL or a staging version that was never updated. The page still gets crawled, but Google treats the other URL as the one to index. That means the visible page loses its ranking signals.
Wrong URLs are even more common. A canonical tag that points to a page that redirects, returns a 404, or sits behind a noindex directive tells Google to consolidate signals into a dead end. The result is usually a page that drops out of the index entirely, with no obvious error in the page itself.
Multiple canonicals create a different problem. When a page has two rel=canonical tags that point to different URLs, Google has to guess which one you meant. It often ignores both. The same thing happens when a canonical tag appears in the HTML head and a conflicting one is sent through the HTTP header.
Canonical chains are the slowest to notice. Page A points to Page B, Page B points to Page C, and Page C points back to Page A. Each hop dilutes the signal. Google usually resolves the chain, but it wastes crawl budget and can pick the wrong page as the final destination. Keep canonicals to a single, direct hop.
For a deeper look at how these errors show up in practice, the How to Use Google Search Console guide walks through the exact reports where Google flags canonical conflicts.
Verifying Canonicals in Google Search Console
Google Search Console's URL Inspection tool is the fastest way to confirm which page Google has selected as canonical. Paste the URL you want to check into the inspection bar at the top of the property. The tool returns a report with a section called Page indexing, and inside it you'll see Google-selected canonical. If that field shows the same URL you inspected, your canonical tag is working as intended. If it shows a different URL, Google has chosen another page as the canonical version, and you need to find out why.
Mismatches happen for a few common reasons. A missing or malformed rel=canonical tag on the inspected page lets Google fall back to its own signals, which often means it picks the URL with the strongest internal links or the version it crawled first. Conflicting canonical tags, where two pages point at each other, also confuse the system. And sometimes a redirect chain or a parameterized URL set (like session IDs or tracking codes) causes Google to consolidate signals onto a URL you didn't intend.
When you spot a mismatch, open the Page indexing section and look for the Inspected URL row. Google usually explains why it selected a different canonical, citing signals like "Duplicate, Google chose different canonical than user" or "Duplicate without user-selected canonical." That message tells you whether your tag was ignored or never seen. Fix the underlying issue, then click Request indexing to ask Google to recrawl. The Google Search Console guide walks through the full inspection workflow if you want more detail on reading the report. For Google's official documentation on canonicalization, see Google's guide to canonicalization.
For sites with many pages, checking canonicals one by one doesn't scale. Serfix pulls live Search Console data into a dashboard, so you can filter for pages where the Google-selected canonical differs from your declared canonical URL and work through the list in priority order.
Canonicals and Internal Linking
Internal links do not create canonical signals on their own, but they reinforce them. When Google crawls your site, it builds a map of how pages connect. A consistent internal linking pattern tells the crawler which URL you consider the primary version. If your navigation, footer links, and in-content links all point to the same canonical URL, the signal is clear. If some point to a trailing-slash version and others to a non-trailing-slash version, you are sending mixed messages.
This matters most on large sites where the same product or article appears under multiple URLs. A category page might link to /blog/seo-tools while a tag page links to /blog/seo-tools/. Both URLs resolve, but only one should be canonical. When your internal links consistently use the canonical URL, Google spends less crawl budget reconciling duplicates and more time indexing the pages that actually matter.
Sitemaps work the same way. The URLs you list in your XML sitemap should match the canonical URLs you declare with rel=canonical. A mismatch here is a common source of indexing confusion. If your sitemap lists /products/blue-widget but the page declares /products/blue-widget?color=blue as canonical, Google has to resolve the conflict. Usually it picks one, but you have wasted crawl budget and introduced uncertainty.
Serfix's site audit flags internal links that point to non-canonical URLs, so you can fix inconsistencies before they compound. The same audit checks whether your sitemap entries align with your declared canonicals. Fixing these mismatches is one of the lowest-effort, highest-impact technical SEO tasks you can do.
Automating Canonical Checks with Serfix
Manual canonical audits fall apart at scale. A site with 500 URLs can hide dozens of duplicate-content signals across pagination, parameter variants, and trailing-slash differences. Serfix's technical audit engine crawls every page and flags missing, conflicting, or self-referencing canonicals in one pass, so you see the full map instead of spot-checking a handful of URLs.
The audit report groups issues by severity. A page that points its rel=canonical to a 404 target gets a high-priority flag because Google will likely ignore the directive. A canonical URL that redirects through a chain before resolving gets flagged too, since each hop weakens the signal. Serfix also catches pages with no canonical at all, which is common on older WordPress themes that only output the tag when a plugin is active.
Fixing these issues is where the workflow speeds up. Instead of exporting a CSV and manually editing templates, you can route the flagged URLs into Content AI Autopilot for bulk cleanup. The tool suggests the correct canonical URL for each page based on your sitemap and internal-link structure, then applies the rel=canonical tag consistently across the affected templates. That removes the guesswork when two product pages share near-identical descriptions but serve different regions.
Serfix also re-crawls after changes, so you can confirm the fix took effect without waiting for a manual recheck. The before-and-after view in the audit dashboard shows which canonical URLs Google has since accepted, which helps you prioritize the remaining work. For teams managing multiple sites, the same audit runs across every property in the account, giving you a single place to track canonicalization SEO health.
Frequently Asked Questions
What is a canonical tag?
A canonical tag is an HTML element that tells search engines which version of a page is the preferred one when similar or duplicate pages exist. It uses the rel=canonical attribute in the page's head section to point to the canonical URL, consolidating ranking signals.
How do I find the canonical URL of a page?
Open the page in a browser, right-click, and select View Page Source. Search for rel=canonical in the HTML head. The href value is the canonical URL. You can also check with Google Search Console's URL Inspection tool, which shows the Google-selected canonical.
What is the difference between a canonical tag and a 301 redirect?
A 301 redirect sends users and bots to a different URL, while a canonical tag is a hint that search engines can choose to ignore. Redirects are stronger for consolidating authority, but canonicals work when you need to keep both pages accessible to visitors.
Can I use a canonical tag across different domains?
Yes. A cross-domain canonical tag points from a page on one site to a preferred page on another domain. Google supports this when the content is genuinely duplicated or syndicated, and it helps consolidate ranking signals to the original publisher's page.
Does a canonical tag pass link equity?
Yes, in most cases. When you set a canonical URL, Google consolidates signals like backlinks from the duplicate pages to the canonical version. This helps the preferred page rank better, though the transfer is not always a perfect one-to-one pass of authority.
What happens if I don't use canonicals?
Without canonicals, search engines may split ranking signals across multiple duplicate pages. Google will usually pick a canonical on its own, but it might choose the wrong version. That can dilute your rankings and waste crawl budget on near-identical URLs.
Should I use a self-referencing canonical tag?
Yes. A self-referencing canonical tag points to the page's own URL. It's a best practice because it makes the preferred version explicit, even if no duplicates exist. Most SEO plugins, including Serfix's automated checks, flag pages missing this tag.
How long does it take for Google to process a canonical tag?
It varies. Google usually recrawls and respects a new canonical tag within a few days to a few weeks, depending on crawl frequency. For faster results, submit the canonical URL in Google Search Console and ensure internal links point to the same version.